Grok 4.7 vs Grok 4.6: Same $2/$6, and the Board Splits by Job
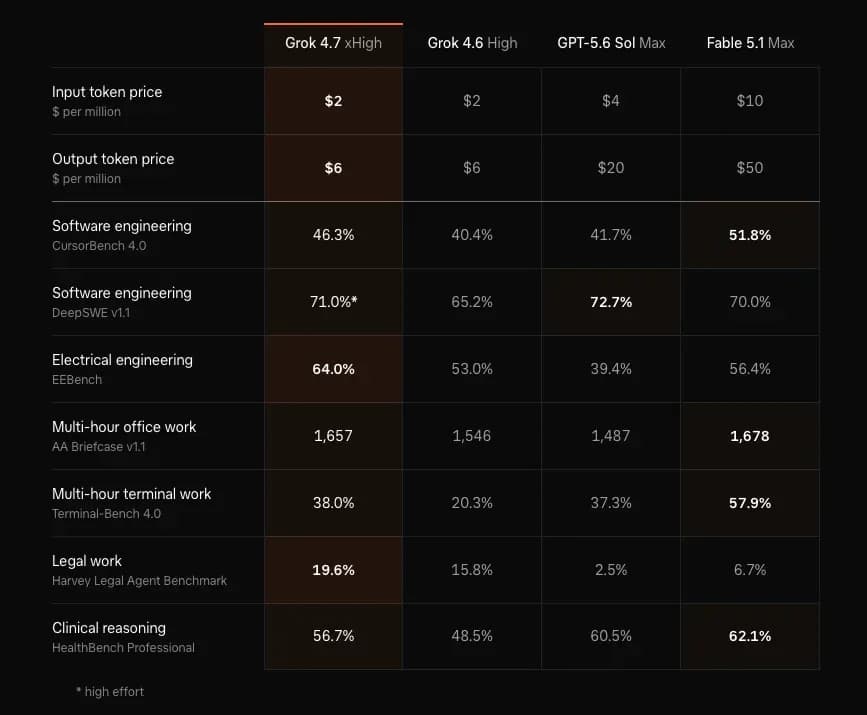
Grok 4.7 shipped on 21 September 2026 at $2 per million input tokens and $6 per million output, the same card as Grok 4.6. SpaceXAI's own scoreboard gives 4.7 every row against 4.6, then loses four of those seven rows to Fable 5.1 Max. We saved both charts from the launch page and sent 12 graded calls through OpenRouter on 22 September, 14:51 to 14:53 UTC.
Where Grok 4.7 actually beats Grok 4.6
Route electrical, legal-agent, and terminal work to Grok 4.7, and leave clinical items on Fable 5.1 or GPT-5.6 Sol.
Every figure in the leader column is from the 21 September launch post, retrieved 22 September 2026. The last row is ours.
| Workload | Leader on that row | Grok 4.7 | Route |
|---|---|---|---|
| EEBench | Grok 4.7 xHigh | 64.0% | Grok 4.7 |
| Harvey legal agent | Grok 4.7 xHigh | 19.6% | Grok 4.7, and tell the user 80.4% still miss |
| Terminal-Bench 4.0 | Fable 5.1 Max, 57.9% | 38.0% | 4.7 when leaving 4.6; Fable when the score is the product |
| CursorBench 4.0 | Fable 5.1 Max, 51.8% | 46.3% | Fable, unless $6 output beats a 5.5 point gap |
| DeepSWE v1.1 | GPT-5.6 Sol Max, 72.7% | 71.0% at high, not xHigh | Sol, or 4.7 if 1.7 points is not worth $20 output |
| AA Briefcase v1.1 | Fable 5.1 Max, 1,678 | 1,657 | Fable by 21 Elo, or 4.7 when the output bill dominates |
| HealthBench Professional | Fable 5.1 Max, 62.1% | 56.7% | Fable or Sol (60.5%), not 4.7 |
| Four short calls, ours | Tie | 4/4 | Keep the client you have |
Grok 4.6 High sits under 4.7 on all seven published rows. That is the whole upgrade case against the model you already run. It is not an upgrade case against Fable on editor tasks, office work, terminal work, or clinical items.
What SpaceXAI's two charts count
The orange column is xHigh, the API default is high, and DeepSWE's 71.0% is marked high.
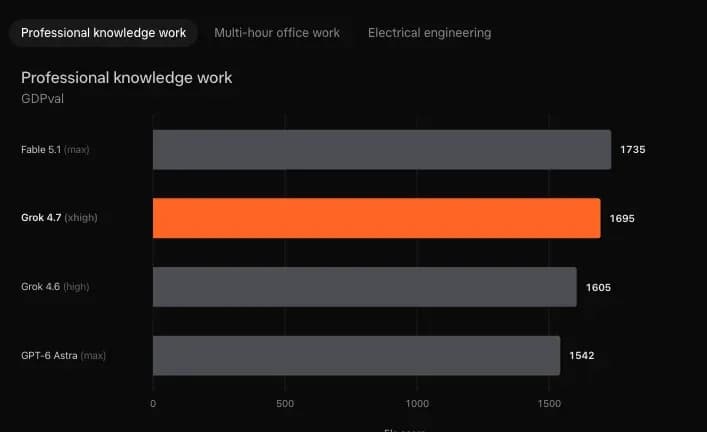
GDPval puts Fable 5.1 max at 1,735 Elo, Grok 4.7 xhigh at 1,695, Grok 4.6 high at 1,605, and GPT-6 Astra max at 1,542. That is +90 Elo on 4.6, 40 Elo behind Fable, and 153 Elo ahead of Astra. The OpenAI name on this chart is Astra. The OpenAI name on the scoreboard is GPT-5.6 Sol Max. They are different models, and the launch page uses both.
- Read the orange column as xHigh. docs.x.ai sets the default effort to high.
- Read 71.0% as high effort. The asterisk sits on that DeepSWE cell and on no other Grok 4.7 cell.
- Keep Astra's 1,542 on the Elo chart. Do not paste it into Sol's column.
Artificial Analysis splits the office-work gain. On AA-Briefcase, analytical quality moved from 1,690 Elo on Grok 4.6 high to 1,994 on Grok 4.7. Presentation quality moved from 1,519 to 1,499. The documents got sharper in the analysis and slightly worse as documents.
CursorBench is Cursor's suite. SpaceX agreed to buy Cursor's maker, Anysphere, for $60B in stock on 16 June 2026.
Grok 4.7 is on the API as grok-4.7, in Cursor, and as the default model in Grok Build. The 12 August write-up of Grok 4.6 vs Grok 4.5 said 4.7 had not shipped yet. That sentence was true on 12 August. It stopped being true on 21 September.
What $2 and $6 leave off the card
A 250,000-token prompt is billed at $4 and $12, on every token in the request.
The chart prints $2 and $6. The models page prints two rows. Under 200,000 prompt tokens the rates are $2 input, $0.50 cached input, and $6 output. At 200,000 or above, the whole request reprices to $4, $1, and $12.
prompt, output = 250_000, 2_000
chart_rate = prompt / 1e6 * 2 + output / 1e6 * 6     # $0.512
cliff_rate = prompt / 1e6 * 4 + output / 1e6 * 12    # $1.024
Crossing the line doubles a bill the chart never shows. $0.512 becomes $1.024. The tokens under 200,000 do not keep the cheap rate.
Input at $2 is half of GPT-5.6 Sol's $4 and a fifth of Fable 5.1's $10. Output at $6 is 3.3× cheaper than Sol's $20 and 8.3× cheaper than Fable's $50. Per output dollar that is 166,667 tokens on Grok, 50,000 on Sol, and 20,000 on Fable. "Half the price" matches the input row against Sol. It does not match either output row.
Cached input stays $0.50 per million under 200,000 tokens, the same figure as Grok 4.6, then $1 at the cliff. How that cache line hits a real invoice is the subject of the inference cost guide.
Grok 4.7 Fast is a separate switch: twice the output speed at twice the token price, inside Cursor and Grok Build. It is not the 200,000-token cliff, and the public API does not sell it.
Artificial Analysis clocked long prompts at about 188 tokens per second and about 7.1 minutes per Intelligence Index task. Our short-call median was 5.02 seconds for Grok 4.7 high against 8.12 seconds for Grok 4.6 high. Neither figure is a 2× speed claim against Fable or Sol.
What 12 Grok 4.7 calls returned on 22 September
Twelve calls scored 12/12, and xhigh returned the same four answers as high.
Same four prompts, temperature 0, max_tokens 4000, one trial each, no tools. Grok 4.6 at high, Grok 4.7 at high, Grok 4.7 at xhigh. The gateway was OpenRouter, which is the setup in our LLM gateway comparison. Raw usage objects are in benchmark-raw.json next to this post. OpenRouter's usage.cost for the twelve calls summed to $0.029279.
{
  "model": "x-ai/grok-4.7",
  "temperature": 0,
  "max_tokens": 4000,
  "reasoning": {"effort": "xhigh"},
  "messages": [{"role": "user", "content": "..."}]
}| Task | Expected | 4.6 high | 4.7 high | 4.7 xhigh |
|---|---|---|---|---|
| Median of 3, 1, 4, 1, 5, 9 | 3.5 | 3.5, 6.17 s, 348 tok | 3.5, 5.42 s, 359 tok | 3.5, 4.67 s, 300 tok |
| 2.2 kΩ at 5 mA | 11 V | 11, 8.06 s, 511 tok | 11, 4.62 s, 273 tok | 11, 5.31 s, 348 tok |
| Retry 429 and 503, never 500 | 429,503 | 429,503, 78.30 s, 451 tok | 429,503, 3.37 s, 216 tok | 429,503, 2.07 s, 87 tok |
count_passed([59, 60, 100, 0]) with the loop starting at index 1 | 2 | 2, 8.18 s, 466 tok | 2, 6.10 s, 409 tok | 2, 5.16 s, 368 tok |
Completion tokens fell from 1,776 on Grok 4.6 high to 1,257 on Grok 4.7 high and 1,103 at xhigh. Reasoning tokens, included in those completion counts, were 1,543, then 1,052, then 944. The OpenRouter invoice moved with them: $0.012258, then $0.008877, then $0.008144. That is 29.2% fewer completion tokens at high, and a 27.6% smaller bill, on a test both models finished 4/4.
prompt_tokens on Grok 4.7 came back exactly 1,036 above the matched Grok 4.6 call at high: 1,311 against 275, 1,288 against 252, 1,295 against 259, 1,339 against 303. xhigh added one more on each call. At $2 per million, 1,036 tokens are $0.002072. The median item billed $0.002446 on 4.6 and $0.002438 on 4.7 high, so the gap missed the invoice. Grok 4.6's four bills do match $2 and $6 on the returned counts. There is no line item for the extra thousand.
The 78.30 second trial is one prompt, one try. Grok 4.7 high answered that same retry-set prompt in 3.37 seconds, xhigh in 2.07 seconds, all three with 429,503. Median latency across the four prompts was 8.12 s, 5.02 s, and 4.92 s. Do not promote the single slow trial into a speed ratio.
On long work the token picture flips. Artificial Analysis reported about 81,000 output tokens per Intelligence Index task for Grok 4.7 at xhigh, against about 36,000 for Grok 4.6 at high. Our 316-token median describes four short answers. It does not describe a multi-hour briefcase.
Where the 38% terminal score comes from
Three published Terminal-Bench 4.0 figures disagree: 38.0%, 33%, and a 4.5 point rise.
- xAI's launch table, the screenshot above: Grok 4.7 xHigh 38.0%, Grok 4.6 High 20.3%, GPT-5.6 Sol Max 37.3%, Fable 5.1 Max 57.9%. Against 4.6 that is 1.87×, or +17.7 points. Against Sol it is +0.7 points. Fable leads by 19.9 points.
- Artificial Analysis, Grok Build as the agent, 21 September 2026: Terminal-Bench 4.0 from 18% to 33%, and DeepSWE v1.1 from 65% to 73%. Their Coding Agent Index moved from 47 to 56 and landed fourth, behind Fable 5.1, GPT-6 Astra, and Claude Opus 5.
- The same lab's Intelligence Index, one shared runner for every model: Terminal-Bench 4.0 up 4.5 points, and the index up 2 points to 46. AA-LCR fell 3.7 points. AutomationBench-AA fell 1.1 points.
xAI does not name the agent behind the 38.0%. Budget the figure that matches your client. The Fable 5.1 review records 55.8% for Fable on Terminal-Bench 4.0, against 57.9% on this board. Astra's coding index belongs in the GPT-6 Astra piece. This page only needs the 1,542 Elo bar.
Which workload should leave Grok 4.6
Short structured calls can stay, and terminal, electrical, and legal-agent jobs should move.
Fable still leads CursorBench 4.0 by 5.5 points, 51.8% against 46.3%. HealthBench Professional still has Fable at 62.1% and Sol at 60.5%, with Grok 4.7 at 56.7%. Those two rows are why "switch everything" is the wrong order.
| If the job looks like this | Keep | Move to Grok 4.7 when |
|---|---|---|
| A short graded transform, like the four prompts above | The model already wired in | The completion-token bill is the only complaint. Ours dropped 29.2% at high |
| Shell work in the shape of Terminal-Bench 4.0 | Fable 5.1, if 57.9% is the requirement | You are leaving Grok 4.6's 20.3% and can live at 38.0% |
| Circuit and unit work in the shape of EEBench | Nobody on this board beats 64.0% | Always, on this table |
| A legal-agent loop in the shape of Harvey | Nobody on this board beats 19.6% | Always on this table, with the 80.4% miss rate in the contract |
| Multi-hour documents, AA Briefcase | Fable, 21 Elo ahead at 1,678 | Output price dominates: $6 against Fable's $50 |
| Editor tasks, CursorBench 4.0 | Fable at 51.8% | A 5.5 point gap is cheaper than an 8.3× output rate |
| Clinical items, HealthBench Professional | Fable or Sol | Do not move for the score. 56.7% trails both |
Fable's $50 output rate is 8.3× Grok's $6. Pay that multiple when the row is the product. The same choice, written as a router config, is in the model routing guide. Harvey's 19.6% leads this board and still misses 80.4% of the set.
What this measurement cannot tell you
Four prompts, one trial each, say nothing about CursorBench 4.0 or a 7-minute office task.
- Temperature was 0,
max_tokenswas 4000, tools were off, and nothing was retried. A second trial on the 78.30 second call might have been ordinary. - Fable 5.1, GPT-5.6 Sol, and GPT-6 Astra were not called. Their cells are quoted from xAI and from Artificial Analysis.
- The 1,036-token prompt gap is an accounting fact. Nothing in the response names those tokens, and the invoice did not add the $0.002072 list-price value.
- Artificial Analysis recorded regressions, not only gains: AA-LCR down 3.7 points, AutomationBench-AA down 1.1, presentation quality on AA-Briefcase down from 1,519 Elo to 1,499.
- AA-Omniscience accuracy was 47% for Grok 4.7 against 48% for Grok 4.6 high. The hallucination rate on that set fell from 34% to 29%.
Ship 4.7 where the row moved and the absolute rate can sit next to a customer's name. Leave clinical items on Fable or Sol. Leave xhigh off until a graded task changes its answer. These four did not.
Frequently Asked Questions
What is Grok 4.7's knowledge cutoff?
docs.x.ai dates the cutoff at May 2026. This 21 September release is not in the weights. Web search and X search are separate tools on that same page. A request without them answers from May 2026. Pass the source in the prompt when the fact is newer than that.
Does the US endpoint change the token price?
The US regional base URL is https://us.api.x.ai/v1. docs.x.ai prices it at a 10% premium so inference stays in the United States. A $6 output token becomes $6.60 there, and a $2 input token becomes $2.20. The model id is still grok-4.7. The 200,000-token cliff and the cached-input rate still apply on top of that premium.
Can the API take an image?
Yes. The model page lists text and image input with text-only output, a 500,000 token context, and no text output cap. Accepted images are jpg or png, up to 20 MiB each, with no stated cap on count. The reply is text. Image generation stays on the Imagine models and their own price list.
Where does Grok 4.7 Fast actually run?
Fast is the same weights on quicker machines, at twice the token rates: $4 input and $12 output off the standard card. docs.x.ai sells it in Cursor and Grok Build, and leaves it out of the Grok Build free tier. The public API does not list it. API traffic stays on $2 and $6, cliff included.
Which model string should the SDK send?
On the xAI API the string is grok-4.7. On OpenRouter we called x-ai/grok-4.7 on 22 September 2026. Set reasoning.effort to low, medium, high, or xhigh. High is the documented default. The orange column is xhigh, so a client that omits the field is not that column.