AI that runs on your own servers.

Open models such as Llama, Mistral and Qwen, served with vLLM or Ollama on your hardware or in your private cloud. Prompts, documents and answers never leave your network, so privacy law in your country stays simple. We size the hardware, build retrieval over your internal data, fine-tune where it pays and hand over a system your IT team runs.

of prompts or documents leave your network
0 B
to a working assistant on your own data
2–4 wk
of the models, weights and code on your hardware
100%

Private inference

Running on your hardware, no internet required

Llama 3.3 70B · vLLMgpu-01 · your data center

Question from Finance

Summarise the supplier contract with Acme and list the termination clauses.

Retrieved from internal documents

  • contracts/acme-supply-2025.pdf · pages 3, 11
  • legal/termination-policy.docx · section 4

Answer

Latency 1.4 s

  • Three-year supply agreement from March 2025, 60,000 units per quarter at a fixed unit price.
  • Either side may terminate with six months' notice after the first year [1].
  • Immediate termination is allowed on a material breach not fixed within 30 days [1][2].

Data left the network0 B

Logged to your audit trail

CIOs, CTOs and data leads run local AI with us.

Same engineers, same process. Which use case goes first depends on who is asking and what their policy allows.

CIO / Head of IT

Before
Legal said no to cloud AI. Our customer data cannot leave the building, so my teams are using nothing or using it in secret.
After
A model on your own servers behind your SSO, with every prompt logged. Your teams get the assistant they already wanted, and the data map in the documentation answers the auditor.

0 Bof data leave your network
CTO / Head of Engineering

Before
We pay per token for an API, the bill grows every month, and we still cannot send it customer records.
After
A sizing table with your real cost per token on your own GPUs, then a serving stack that replaces the API behind one gateway. Same calls from your code, no per-token bill, and customer records allowed.

2–4 wkto the first use case live

Head of Data / Operations

Before
Our documents are in German and Turkish and full of our own terms. Generic models answer them badly.
After
Retrieval over your documents in their languages, a fine-tune on your examples when the evals show a gain, and answers with the source page attached. Measured on your real questions before launch.

100%of the weights and code yours

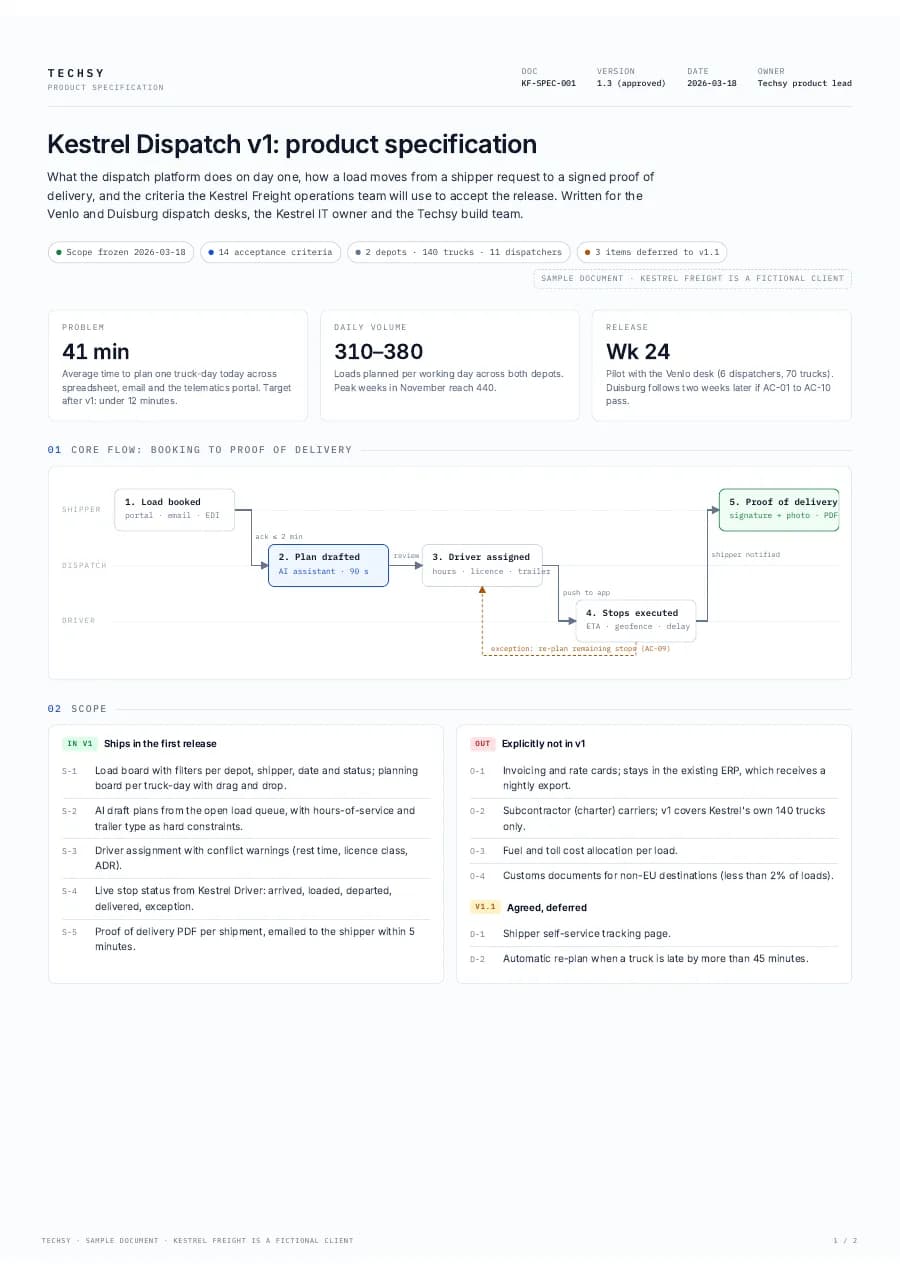
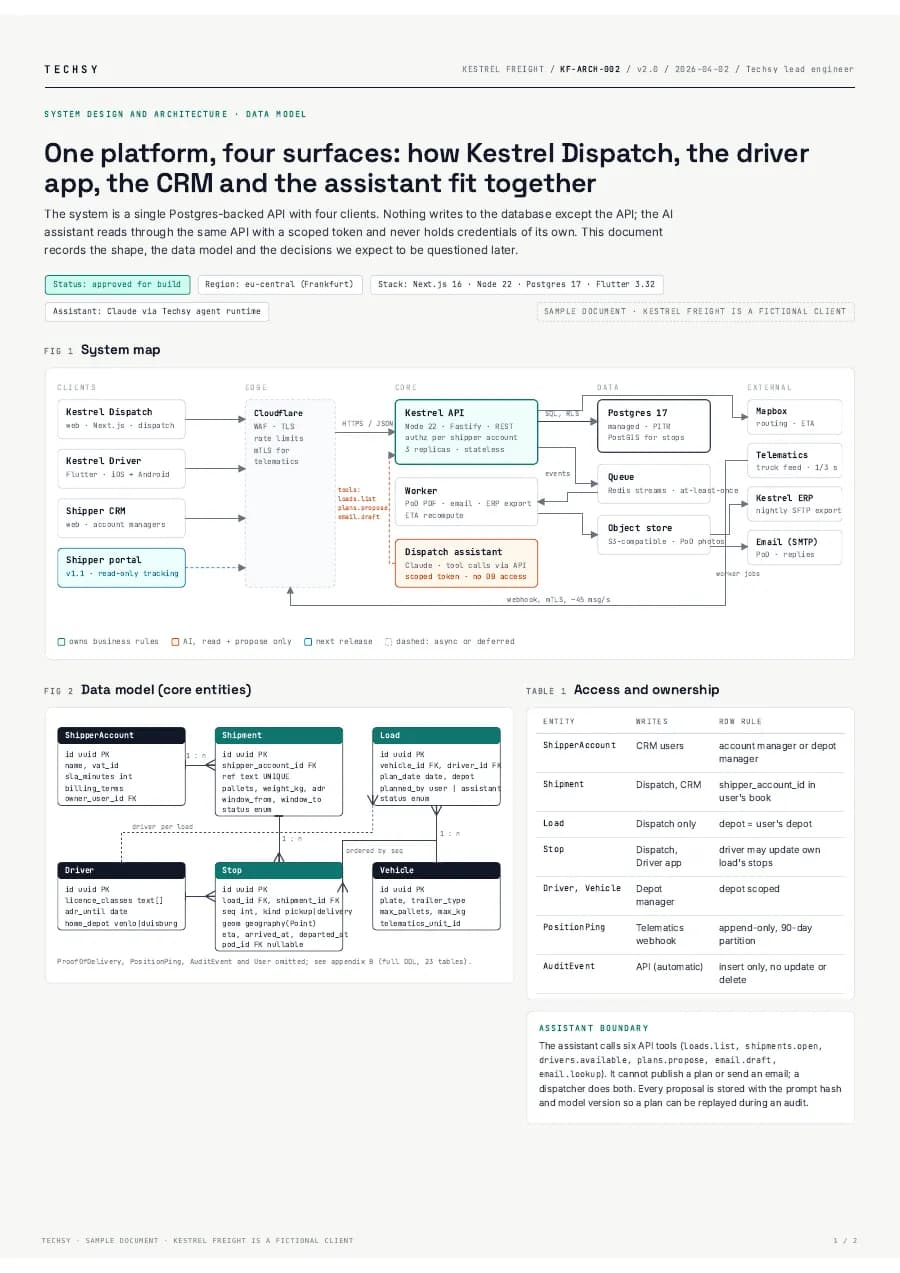
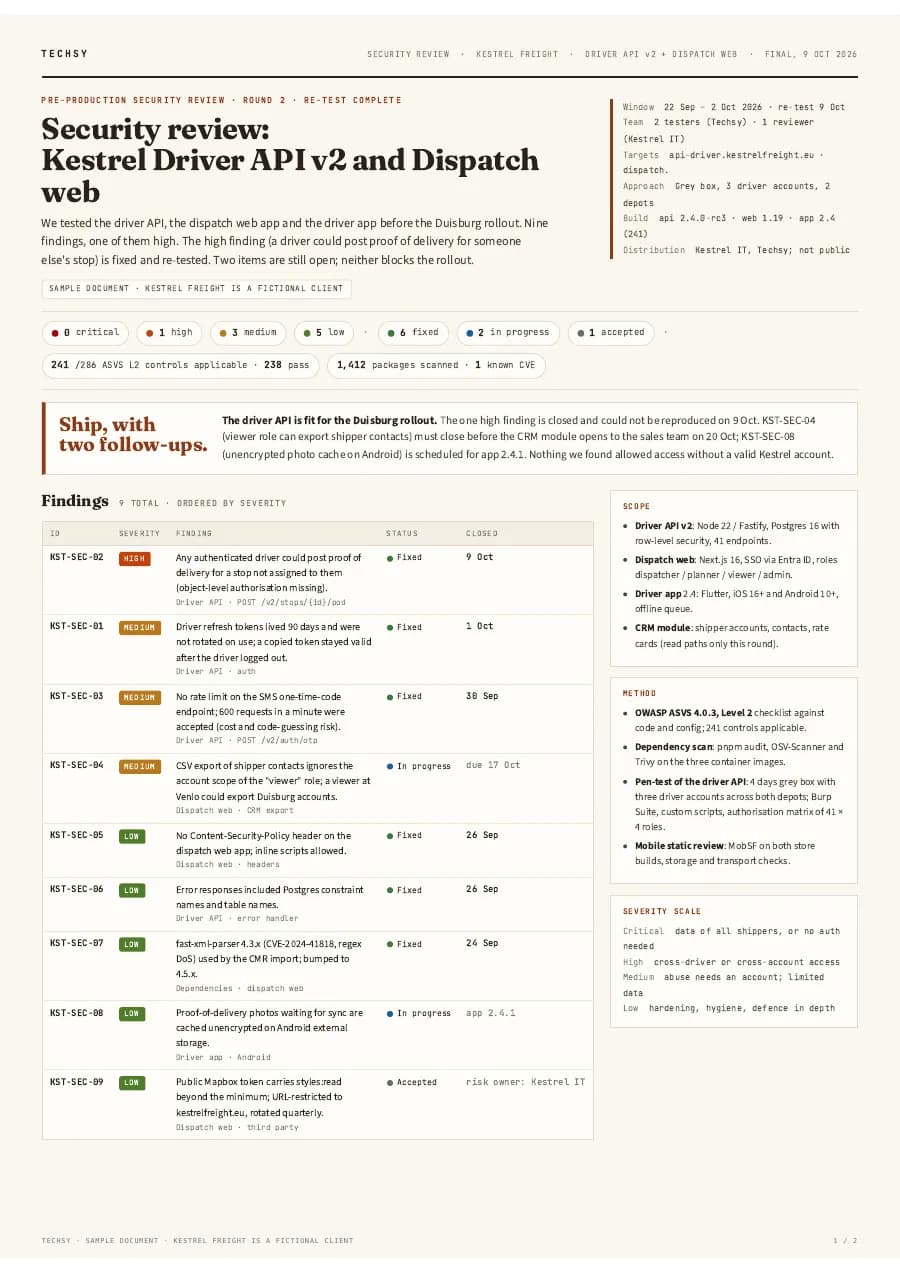
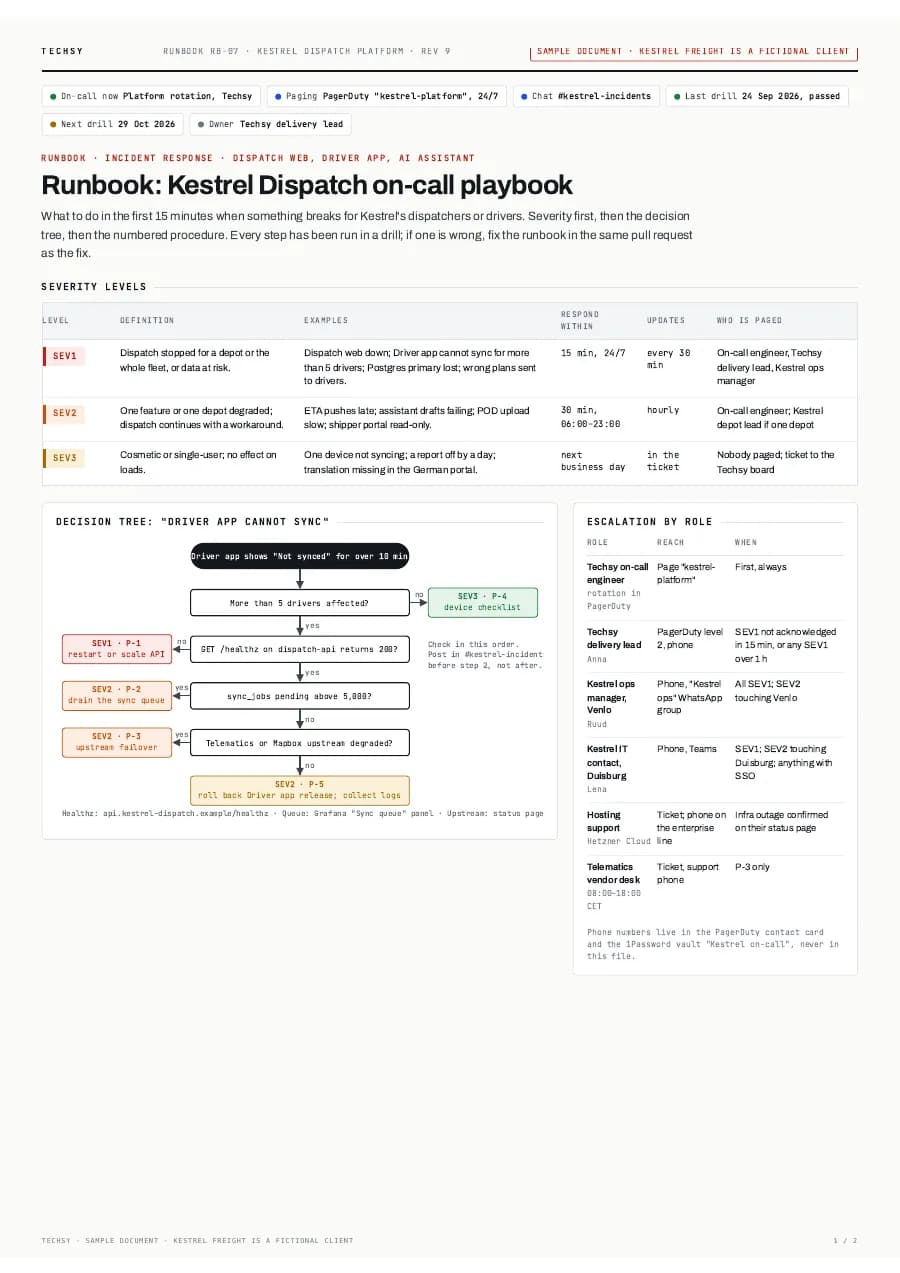
We build, test and hand over local AI on your hardware.

  • 01

    The inference stack

    vLLM or Ollama serving an open model, a gateway with the same API shape your code already calls, GPU scheduling, caching and monitoring. On one server, a cluster or your private cloud.

  • 02

    Retrieval over your internal data

    Connectors to your file shares, wikis, databases and ticket systems. Embeddings and the index stay local, retrieval respects your access rules, and every answer cites the document and page.

  • 03

    Fine-tuning where it pays

    A LoRA fine-tune on your own examples when the evals show a gain: your format, your vocabulary, your languages. Trained on your hardware; the weights are yours.

  • 04

    Hardware sizing and the runbook

    A sizing table with cost per token, the GPU plan, failover and backup, and a runbook your IT team uses to update models, roll back and read the monitoring.

Included free

5 documents ship with the entry package.

The same folder you see on the pricing page. Open any one to read a sample first page.

All of these documents come free with the package; none of them adds a line to your plan.

  • Need something else?Just ask. We add it to your package, free.

Your first local AI use case runs in two to four weeks.

You bring the use case, the documents and an hour a week. We size, build, measure and hand over, and your IT team is in every step from the first server onward.

  1. 01

    Week 1

    First meeting and sizing

    We
    A free first meeting about the use cases and the data. Then a research report: data map, model shortlist, hardware sizing with cost per token, and a fixed price.
    You
    Approve the plan and pay 50%. Order the hardware, or point us at the private cloud you already have.
  2. 02

    Weeks 2–3

    Pilot on one use case

    We
    Serve the model on your first node, connect one document source, build retrieval with citations and write the evals from your real questions.
    You
    Hand us 50 to 100 real questions with the answers you expect.
  3. 03

    Weeks 3–6

    Harden and extend

    We
    SSO and access rules, the prompt and answer log, monitoring, failover and backups. Fine-tune if the evals show a gain. Add the next use case.
    You
    Review the eval scores with us and sign off on the thresholds.
  4. 04

    Launch

    Handover to your IT

    We
    Runbook, training for your IT team, and the remaining 50% at delivery. Larger platforms run up to three months on the same terms.
    You
    Run it yourself, or keep us on a monthly plan for model updates and eval reruns.

Start with a private assistant. Grow into a private AI platform.

Three packages, each at a fixed price you see before you commit. Each one builds on the one before, so nothing is thrown away.

  1. 01

    First meeting

    30 minutes, free

    You describe the use case and where the data lives. We tell you which model and hardware fit, what the entry package costs and what the API bill would be instead.

  2. 02

    Private AI assistant

    Live in 2 to 3 weeks

    An open model on your own server. Nothing leaves your network.

  3. 03

    Private knowledge base

    Live in 3 to 5 weeks

    Your documents searchable by AI, entirely inside your network.

  4. 04

    Enterprise private AI

    Live in 6 to 10 weeks

    Several departments on one private AI platform.

Local AI runs on your servers and signs in through your SSO.

We build on the hardware and accounts you already own, sign users in through your SSO and send metrics to the monitoring you already watch.

Anything else with an API: we write the connector and hand you the code.

Private cloud

  • AWS
  • Google Cloud
  • Azure
  • Cloudflare

Identity and access

  • Okta
  • Microsoft Entra ID
  • Auth0

Data sources

  • PostgreSQL
  • Supabase
  • Notion
  • SAP
  • Dynamics 365
  • Odoo

Monitoring

  • Grafana
  • Datadog
  • Sentry
  • Elastic

Use it with any AI tool.

The agents, skills and code we hand over work in the tools your team already uses.

  • Codex
  • Claude
  • Cursor
  • Grok
  • Z.ai
  • Hermes
  • OpenClaw
  • Eve
  • Mistral
  • OpenCode
  • VS Code
  • Antigravity
  • Windsurf
  • JetBrains
  • Zed
  • GitHub Copilot
  • Cline
  • Qwen
  • Amp
  • Goose
  • Lovable
  • Replit
  • v0

Your local AI package has one fixed price.

  • Lowest price

    Private AI assistant

    An open model on your own server. Nothing leaves your network.

    $4,500

    $3,000

    Starting price · one-off payment

    • 5 documents, free
    • An open model, such as Llama or Qwen, on your server
    • Team chat with logins
    • Your data never goes to an outside AI provider
    • Hardware sizing and a setup guide
    • A security review of the setup
  • Most popular

    Mid-range

    Private knowledge base

    Your documents searchable by AI, entirely inside your network.

    $12,000

    $8,000

    Starting price · one-off payment

    Everything in Private AI assistant, plus:

    • Your documents connected, with permissions
    • Answers with their sources
    • Single sign-on with your company accounts
    • Quality tests on your own questions
    • Monitoring and an update plan
  • Top of the range

    Enterprise private AI

    Several departments on one private AI platform.

    $30,000

    $20,000

    Starting price · one-off payment

    Everything in Private knowledge base, plus:

    • Several departments, each with its own data and rules
    • GPU sizing for your load
    • An API for your other systems
    • Audit logs and access reports
    • Quality tests on every model update

Your first meeting with Techsy is free.

You leave understanding what you need.

  • The first meeting costs nothing.
  • The research report is free too.
  • 25% back if you cancel within 28 days.
How a project runs with Techsy, step by step
  1. Free meeting: Thirty minutes with a person who builds.
  2. Planning: Scope, phases and dates, agreed in writing.
  3. Research and docs: A free research report and the specs.
  4. Solution and benefits: What we build and what it saves you.
  5. Development: Built in short cycles you can see.
  6. Launch: Live, monitored and handed over.

Teams ask these questions before running AI on their own servers.

Cost, models, hardware, privacy and who keeps it running. The questions we hear on every first meeting.

  • Three packages. Private AI assistant for $3,000 puts an open model on your own server with a team chat. Private knowledge base for $8,000 adds your documents with permissions, sources and single sign-on. Enterprise private AI for $20,000 serves several departments, with GPU sizing, an API and audit logs. You pay 50% when you approve the plan and the rest at delivery. Hardware is bought in your name; we size it and tell you the cost per token before you order.

  • Open-weight models: Llama, Mistral, Qwen, Gemma, DeepSeek and smaller task models for embeddings, reranking and classification. We pick per use case on eval scores, latency and the hardware you have. A 7B to 14B model on one GPU covers most document and support tasks; a 70B model needs a multi-GPU node. Every model call goes through one gateway, so swapping a model later is a configuration change, not a rebuild.

  • It depends on the model and the number of people using it at once. A single server with one or two data-center GPUs serves a 14B model to a few hundred users. A 70B model wants four to eight GPUs. If you already have GPU capacity, in a private cloud or on a workstation, we start there. The research report includes a sizing table with cost per token, so you can compare it with the API bill you pay today.

  • It removes the hardest part: no personal data leaves your infrastructure, so there is no third-party processor, no transfer outside your country and no provider training on your prompts. We add what auditors ask for: access rules tied to your SSO, a log of every prompt and answer, retention policies and a data map in the documentation. Your legal team still owns the policy; we make the technical answer to every question a yes.

  • On general knowledge, the frontier APIs are ahead. On your documents, your terms and your language, a local model with good retrieval and a small fine-tune usually matches or beats them, because the answer comes from your data, not from the model's memory. We do not ask you to trust that: before launch we run evals on a set of your real questions and show you the scores side by side.

  • Start with retrieval. RAG puts the right documents in front of the model and gives you citations, and it covers most use cases on its own. Fine-tuning pays when the model must learn a style, a format or a domain vocabulary, such as German contract language or Turkish accounting terms. We propose it only when the evals show a clear gain, and we run it on your hardware with your examples.

  • Your IT team can, with the runbook we hand over: how to update a model, roll back, add a GPU, read the monitoring and restore from backup. Many clients keep us on a monthly plan instead: we keep models, drivers and the serving stack current, re-run the evals when your data changes and watch GPU use and latency. Either way, the system is yours and runs without us.

  • The first meeting is free. Within a week you have a research report with the use cases, the data map, the hardware sizing and a fixed price. You approve the plan and pay 50%. A first use case is live on your hardware in two to four weeks; a full platform with several use cases, SSO and fine-tuning takes up to three months. The remaining 50% is due at delivery, after the evals pass the thresholds we agreed.

Didn’t find your answer?

Ask a person

Ship the system your business runs on.

Book a scoping call and we map the build, the cost, and the timeline. Most teams leave the first one with a fixed plan.

Three quick questions, then your price band and timeline. No call needed.